Coding and rendering point cloud video
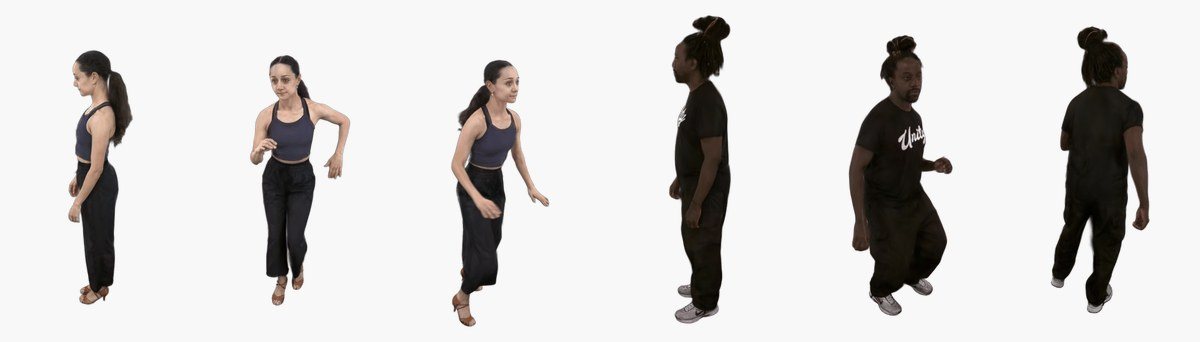
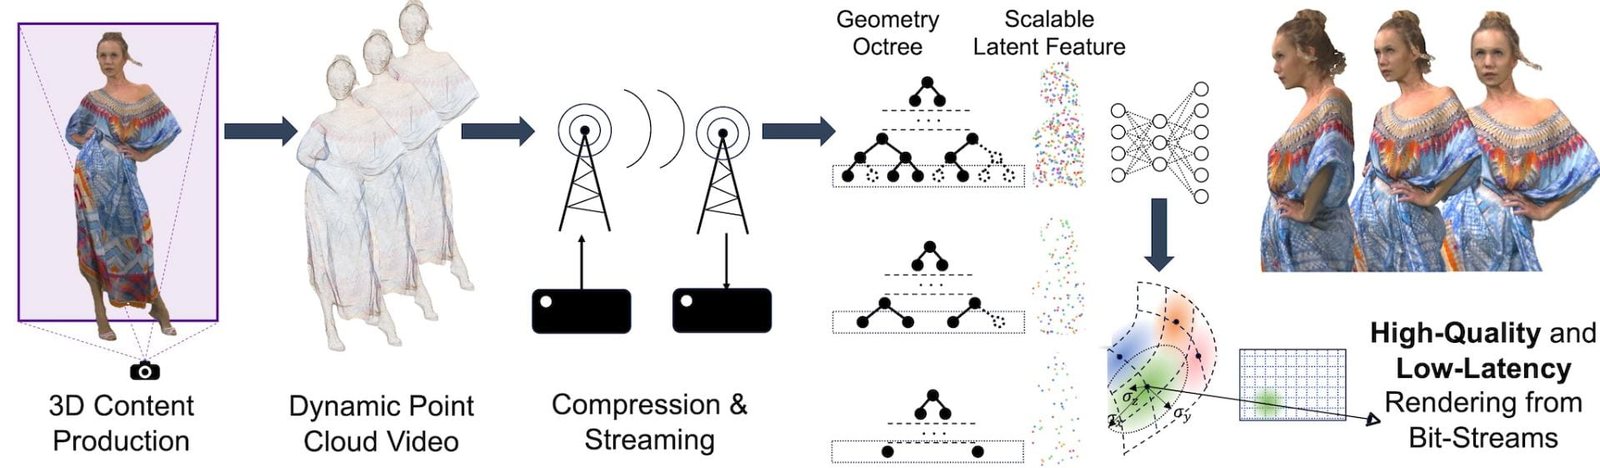
Each frame is coded as an octree for geometry plus scalable latent features, so a receiver can decode at the quality its bandwidth allows. A feed-forward network, P2ENet, turns the decoded points into 3D Gaussians that render in real time on a GPU (Hu et al., CVPRW 2024). Bits-to-Photon trains compression and rendering end to end, so bits go where they most improve the rendered image (Hu et al., ICIP 2025). Follow-on work adds temporal prediction between frames (U-Motion), textured surfel octrees (TeSO) and multi-resolution Gaussian decoding (SplatTree).
Point cloud video is coded as a geometry octree with scalable latent features, which a network decodes into 3D Gaussians for rendering (NYU Video Lab).